The website development process in Dubai: what happens, in what order, and where projects stall
What each stage produces, which one overruns, and the handovers to insist on before paying the next invoice.
Read the articleShopify Integrations
One source of truth, updates that arrive out of order, the difference between available and on hand, reservations, and the reconciliation loop that catches what events miss.
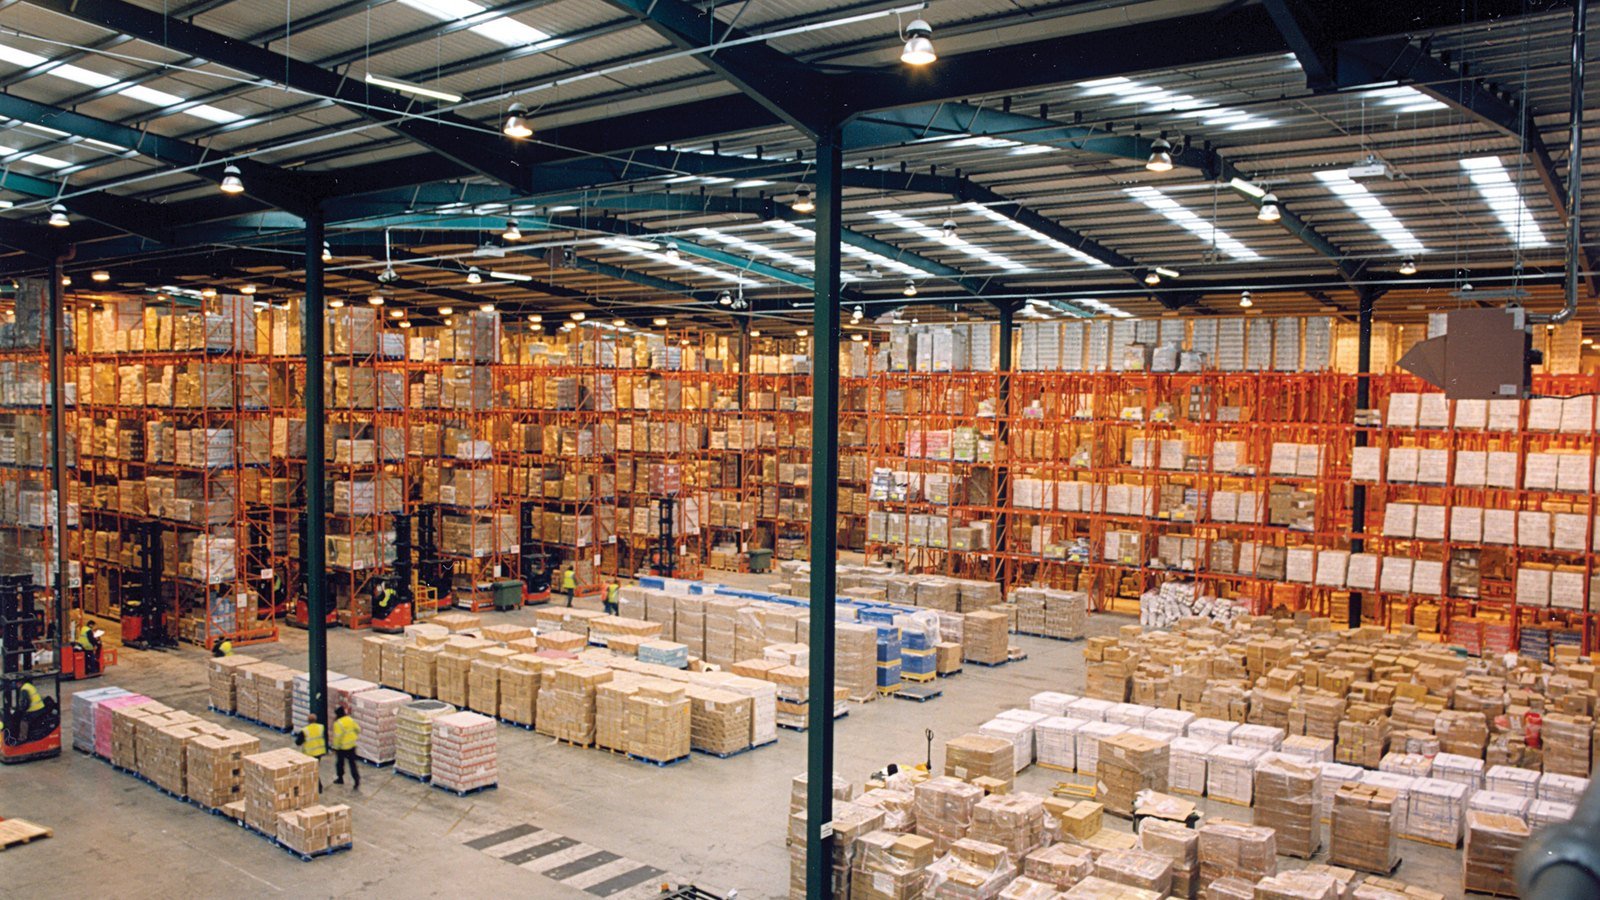
Real time inventory synchronisation is the problem that makes multi system retail genuinely hard. Orders are easy by comparison: an order happens once, in one place, and moves in one direction. Stock is a number that two or more systems believe they know, that changes from several directions at once, and that is wrong in a way customers notice immediately.
This is what actually causes drift, and the patterns that keep it small.
Every real time inventory synchronisation decision follows from this, and it is where most trouble starts, because the answer is usually assumed rather than stated.
If an ERP or POS counts the stock, it is the source. The store receives figures and does not originate them. One direction, no argument.
If the store is the only place stock exists, it is the source. Equally fine, and the other systems take their figures from it.
What does not work is two systems both believing they are authoritative. Each writes to the other, each overwrites the other’s correction, and the resulting oscillation produces figures that are wrong in both places and impossible to reason about. Real time inventory synchronisation with bidirectional authority is the single most reliable way to generate incidents.
Multiple locations need the rule stated per location. One warehouse may be authoritative for its own stock while the shop is authoritative for its shelf. That is coherent. What is not coherent is a pooled figure that either system may write.
Write the rule down in one sentence. If nobody can produce that sentence, the design is not finished.
The most common cause of overselling is not broken real time inventory synchronisation. It is publishing the wrong number.
On hand is what is physically present. Ten units on a shelf.
Committed is what is already promised to orders that have not shipped. Three units, awaiting picking.
Available is what may still be sold. Seven.
A system publishing on hand will sell those three units again. The storefront should always receive available, and the platform’s own model supports this distinction properly.
The subtlety is where commitment happens. If orders are captured in the store and fulfilled in an ERP, there is a window where the store knows about a commitment the ERP does not. During that window the ERP’s available figure is too high, and if it pushes that figure back it will undo the store’s own deduction. Deciding how commitment flows is as important as deciding who owns the count.
This is the most valuable implementation decision in real time inventory synchronisation and it is frequently got wrong for understandable reasons.
An adjustment says: subtract two. It is efficient and it is fragile. Delivered twice, the figure is wrong by two forever. Lost, the figure is wrong by two forever. Nothing in the system can detect either case, because an adjustment carries no information about what the result should be.
An absolute value says: this item is now seven. Delivered twice, harmless. Lost, the next update corrects it. The pipeline becomes self healing, and that property is worth far more than the bandwidth it costs.
Carry a version or timestamp with it. Which leads directly to the next problem.
Real time inventory synchronisation breaks quietly here. Two updates for the same item are generated a second apart. The first says seven, the second says six. They are processed by different workers and the second finishes first. The item is left at seven, permanently, until something else changes it.
This is the defect that produces drift nobody can explain, and it is invisible in testing because tests do not race.
Every update needs a sequence marker. A version number or a source timestamp, generated by the source of truth rather than by the receiver.
The receiver discards anything older than what it has. If the stored version is newer, drop the update. This one rule eliminates the entire class of problem.
Do not use receipt time. The order in which your system received messages is not the order in which they happened, which is exactly the thing going wrong.
Per item ordering is enough. You do not need global ordering, which is expensive. Partitioning work by item so that updates for one item are processed in sequence gives you correctness without the cost.
Real time inventory synchronisation meets its limit here: two customers, one unit, two systems. Somebody is going to be disappointed and the design decides how often.
You cannot fully eliminate it across two systems. Any gap between checking and committing is a window, and distributed systems always have a gap. Claims to the contrary should be treated with suspicion.
You can make it rare. Shorten the interval between the stock changing and the storefront knowing. Publish available rather than on hand. Hold a small buffer on fast moving lines so the storefront stops selling slightly before the shelf empties.
Reserve at the right moment. Committing stock when an order is placed is right. Committing when something enters a basket is usually wrong, because abandoned baskets then hold stock hostage and the released units arrive back unpredictably.
Decide what happens when you are wrong. Somebody will order the unit you do not have. Is it cancelled and refunded, back ordered, or substituted? That is a business decision and it should exist as a process before it is needed at speed.
Size the buffer with evidence. Count how often the published figure was higher than reality over a fortnight. That number sets the buffer, rather than a guess that is either costing sales or not preventing cancellations.
Event driven updates are the right primary mechanism for real time inventory synchronisation. They are not sufficient on their own, and systems built on events alone drift.
Events get lost. A delivery that fails every retry is gone. A subscription removed during unrelated housekeeping stops a stream silently.
Events miss physical reality. Damage, shrinkage, a miscount, stock moved for a display. None of these generate an event anywhere, and all of them change what is actually on the shelf.
So run a reconciliation pass. Periodically compare the full picture in both systems and correct the differences. Daily for most businesses, more often for fast moving stock.
Use the bulk route for the comparison. Reading a whole catalogue by paging is what turns a nightly reconciliation into an all night job; the bulk mechanism is built for it.
Log what it corrected. This is the part people skip and it is where the value is. A reconciliation that quietly fixes four hundred items every night is telling you the event pipeline is broken. One that fixes three is telling you it is healthy. Without the log, both look identical.
Real time inventory synchronisation is expensive to do everywhere and unnecessary for most of a catalogue, so the proportionate approach is to tier it.
Near instant for scarce fast movers. Items where the stock position is genuinely tight and the cost of overselling is high. This is usually a small fraction of the catalogue.
Minutes for ordinary lines. A few minutes of staleness on an item with forty in stock costs nothing.
Hours, or nothing, for deep stock. If you hold hundreds of a thing, publishing a figure from this morning is fine, and publishing availability rather than a number is often better still.
Tiering reduces request volume dramatically, which matters because stock updates are the single largest consumer of capacity in most integrations. Doing less work on items that do not need it is what leaves headroom for the ones that do, a point covered further in rate limit recovery strategies.
Propagation delay. Time from the stock changing at the source to the storefront showing it, and the only honest measure of whether you have real time inventory synchronisation at all.
Reconciliation correction count. How many items the nightly pass had to fix. The health indicator for the event pipeline, and a rising trend is the earliest warning you will get.
Oversell incidents. Counted, with the item and the cause. A handful on scarce items is the system working as designed; a pattern on deep stock lines means something is broken.
Stale write rejections. How often an out of order update was correctly discarded. Confirms the sequencing is doing its job.
And alert on silence. A stock pipeline that stops produces no errors and no symptom until a customer orders something you do not have. A check that expects updates in a window and alarms when none arrive is the one control that catches it.
State the source of truth in one sentence. Publish available rather than on hand. Send absolute values with a version. Discard stale writes. Partition by item. Add a daily reconciliation and log what it corrects. Tier the freshness so effort goes where stock is tight.
That sequence takes most of the pain out of real time inventory synchronisation, and none of it requires unusual infrastructure.
Related reading: designing highly available Shopify integrations for the architecture underneath, circuit breaker patterns for what happens when a dependency fails mid sync, and performance bottlenecks for why the reconciliation pass is slow.
If your stock figures drift and nobody can say why, describe the setup and we will tell you which of the causes above fits.
Straight answers
Absolute quantities, almost always. An adjustment that is applied twice, or lost, leaves the figure permanently wrong with no way to detect it. An absolute value that arrives twice is harmless, and the next one corrects any earlier loss, which makes the whole pipeline self healing.
Because events can be lost, delivered out of order, or applied to a record that changed underneath them, and because physical stock moves without transactions. Drift is normal. A reconciliation pass that compares the two systems and corrects differences is what keeps it bounded.
For fast moving items with tight stock, yes. For most of a catalogue, a few minutes of delay costs nothing. Spending the engineering effort where the stock position is genuinely tight, and accepting delay elsewhere, is the proportionate answer.
On hand is what is physically there. Available is what you may still sell, which is on hand minus anything committed to unfulfilled orders. Publishing on hand rather than available is one of the most common causes of overselling.
Accept that you cannot eliminate it entirely across two systems, then reduce it. A short sync interval, publishing available rather than on hand, and a small buffer on fast moving lines together remove nearly all of it at a cost of a few deferred sales.
Sources
Fixed price, in writing
Got it. Your quote is being written now.
In business hours you will have it within 45 minutes. Check your inbox for the confirmation.
Keep reading
What each stage produces, which one overruns, and the handovers to insist on before paying the next invoice.
Read the article
Queues over direct calls, idempotency as a requirement, graceful degradation, and health checks that notice silence rather than errors.
Read the article
Chatty queries, oversized payloads, bulk reads done one at a time, and webhook handlers doing work they should have queued.
Read the article